MEASURED API PILOT · 6 SYNTHETIC FILES
PDF.co scanned tables to CSV: what our first six files revealed
All six requests returned a CSV. The clear scan still contained merged cells and incorrect numbers. Check both the table structure and the values before using an export for purchasing.
Tested September 15, 2026 UTC · TableProof editorial team · One run per file · This page contains a labeled affiliate link. We may earn a commission if you buy through it.
Download the raw evidence Get the original test scans
What we actually ran
We uploaded six fictional, image-only PDFs to PDF.co: one file from each category in our published corpus. The cross-page case has two pages, making seven pages in total. These cases reuse the fixture-01 line items; they are variations of one fixture family, not six independent businesses.
Every file used the same PDF-to-CSV API endpoint, English OCR, OCRMode Auto and OCRResolution 300, with inline output and synchronous processing. We made one conversion attempt per file, without a template, crop, correction pass or answer-informed parsing. The service version and account plan were not verified. The raw response bodies are included unchanged.
A successful export is not a checked spreadsheet
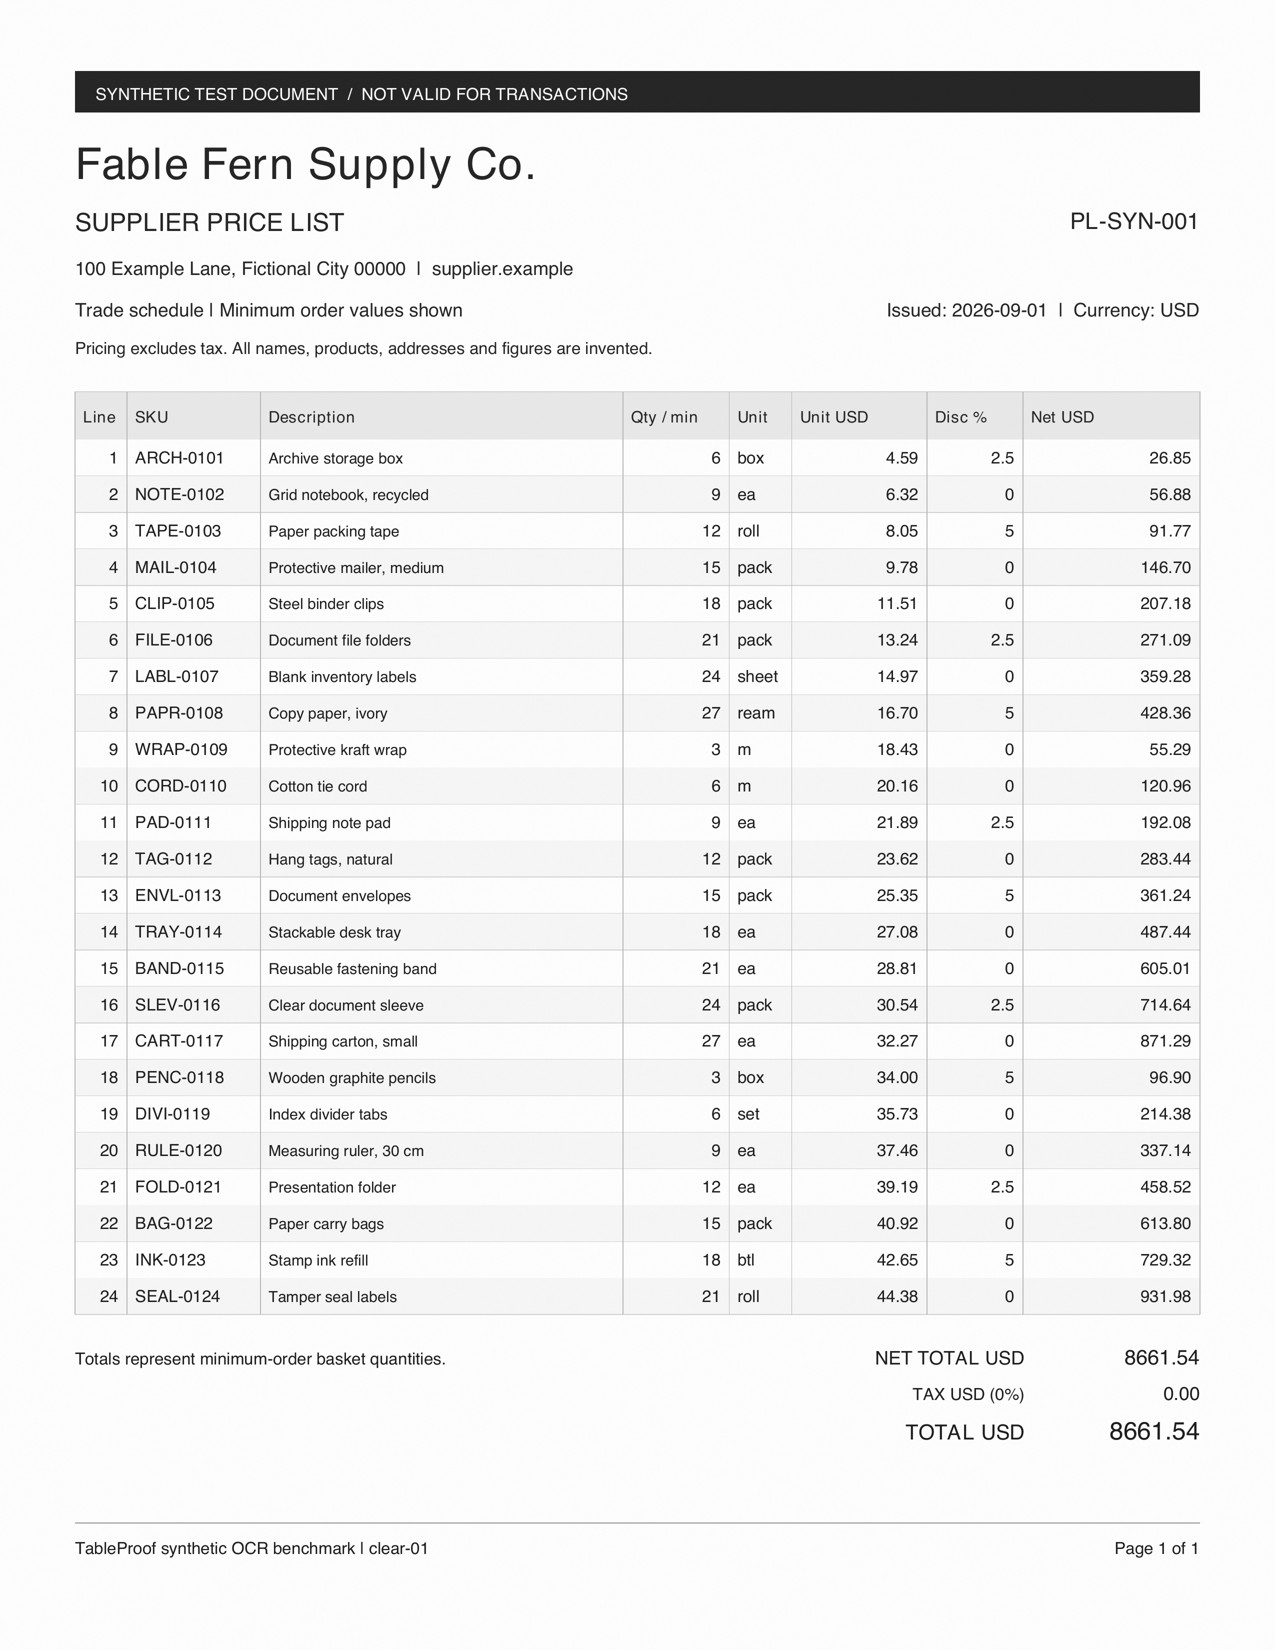
In clear-01, the scan visibly separates Line, SKU and eight table fields. In the CSV, some line numbers merge with SKUs and the record containing the header does not consistently align with the following records. These are selected examples, not an exhaustive error count:
| Source location | Expected | Raw CSV value | Why it matters |
|---|---|---|---|
| Line 1 / SKU | Separate 1 and ARCH-0101 | 1 |ARCH-0101 | A SKU lookup needs a clean identifier column. |
| Line 3 / Net USD | 91.77 | gil.77 | The exported amount is not a decimal number. |
| Line 5 / Unit USD | 11.51 | 11 51 | A missing decimal point needs source review. |
| Line 11 / Disc % | 2.5 | 25 | A valid-looking number can still be wrong. |
Compare the scan preview, raw CSV and standard answer. Parsed CSV records 8, 10, 12 and 18 contain the examples above. We did not silently repair them.
What the other cases showed
The low-resolution file includes TAPE.0103 where the answer is TAPE-0103, and PAD-O111 where the answer is PAD-0111. The skewed output spreads the document over 108 CSV records. The complex-column output spans 65 records. Those record counts include metadata and wrapped content; they are not counts of detected purchase rows.
The two-page output contains records with 13 and 18 CSV fields. A downstream process therefore cannot assume a single consistent raw row width. In the decimal/negative case, negative quantities and amounts were present for the three credit lines, but other issues remained: line 11's discount was exported as 25 instead of 2.5. These observations do not establish a negative-number accuracy rate.
A deliberately limited identifier check
The following check asks only whether each expected SKU appears anywhere in a parsed CSV cell, with case-sensitive alphanumeric/hyphen boundaries. It does not check whether the SKU is in the correct column or paired with the right amount. In particular, clear-01 has every SKU present and still has the errors shown above.
| Sample | SKU strings present | Credits used | Elapsed seconds |
|---|---|---|---|
| Clear scan | 24 / 24 | 35 | 15.927 |
| Low resolution | 20 / 24 | 35 | 11.305 |
| Skewed scan | 23 / 24 | 35 | 11.263 |
| Cross-page headers (2 pages) | 24 / 24 | 63 | 16.094 |
| Complex columns | 24 / 24 | 35 | 13.026 |
| Decimals and negatives | 24 / 24 | 35 | 16.496 |
Elapsed time includes upload, conversion and account checks from this machine. These single observations are not a throughput benchmark. The observed total was 238 credits: 196 reported for conversion and a further 42 across upload steps. We made no new purchase for these tests. We have not verified a dollar cost per credit for this account.
How to use these results
- Try representative scans from your own workflow before committing to batch processing. Include faint scans, decimals, credits and page breaks.
- Inspect the raw column layout before importing it into a purchasing or accounting process. Keep input and output pairs available for review.
- Check identifiers and amounts separately. A complete list of SKU strings does not validate the amounts beside them.
- Include correction time in the processing cost calculator. We have not measured that time yet.
This pilot supports a need for review and extraction setup for this specific corpus and configuration. It does not rank PDF.co against Acrobat or PDFelement, measure all PDF.co modes, or establish performance on real invoices. We have not applied our field scorer to these raw exports because they do not share a stable eight-column schema. A reproducible parsing rule and a separate validation set are needed before reporting field scores.
Reproduce or inspect the evidence
- Evidence ZIP: original CSVs, public run records, token audits and source code
- Machine-readable run summary
- Settings, measurement definitions and limitations
- Input PDFs and standard answers
- Official PDF.co API settings
- Official credit schedule
This site publishes synthetic evidence, not customer files. Public run records omit account information, API credentials and temporary signed URLs. The exact input and output hashes are retained.